
多模型语音合成平台 · Multi-Model Text-to-Speech Platform
六引擎开源语音合成:声音克隆、声音设计、多角色剧本配音,一个 Web UI 全搞定。 Six open-source TTS engines — voice cloning, voice design, multi-character script dubbing — behind one web UI.





治理规范 / Governance: ReSerendipity/.github/governance
TTS MultiModel 是一个自托管的多引擎语音合成(TTS)平台。它把 VoxCPM2、IndexTTS 2.5、IndexTTS 2.0、OpenVoice、Step-Audio-EditX、Breeze TTS 2 六套本地引擎统一到同一个 FastAPI + HTMX Web 界面里,外加一个 Edge-TTS 在线兜底引擎(CPU 可用),让你在一个工作台里完成声音设计、零样本/极致声音克隆、多角色剧本配音、语音转换与音频编辑,而不必在多个工具之间来回切换。
项目代码以 Apache-2.0 开源,本身不打包任何模型权重——权重由你从各模型官方仓库自行下载,使用前请核对每个模型的许可(见下方「模型许可」)。
- 六引擎统一编排:声明式引擎注册表,VoxCPM2 / IndexTTS 2.5 / IndexTTS 2.0 / OpenVoice / Step-Audio-EditX / Breeze TTS 2 灵活切换;Edge-TTS 在线引擎在无 GPU 时自动兜底。
- 声音克隆:少量参考音频即可零样本克隆;「极致克隆」支持参考音频 + 转写文本做更精细的音色还原。
- 声音设计:用自然语言描述目标音色(如「温柔清晰的女声」)直接生成语音,无需参考音频。
- 剧本配音:多角色对话剧本自动分配说话人,逐条试听、批量合成。
- 流式与批量:长文本 SSE 流式输出;批量任务断点续跑,SQLite 记录全部生成历史。
- 多后端与多语言界面:NVIDIA CUDA / Apple MPS / CPU 自动适配;界面支持中文(简/繁)、英文、日文、韩文。

客户端(Web UI / CLI / OpenAI 兼容 API)→ FastAPI 引擎注册表 → 六套本地引擎 + Edge-TTS 在线兜底 → SQLite 历史 / outputs / personas。
以下截图均由源码启动 python app/clean_launch.py(http://127.0.0.1:7869)实拍,未下载模型权重、未触发合成;引擎未加载时空状态如实呈现。
首次启动引导(onboarding)
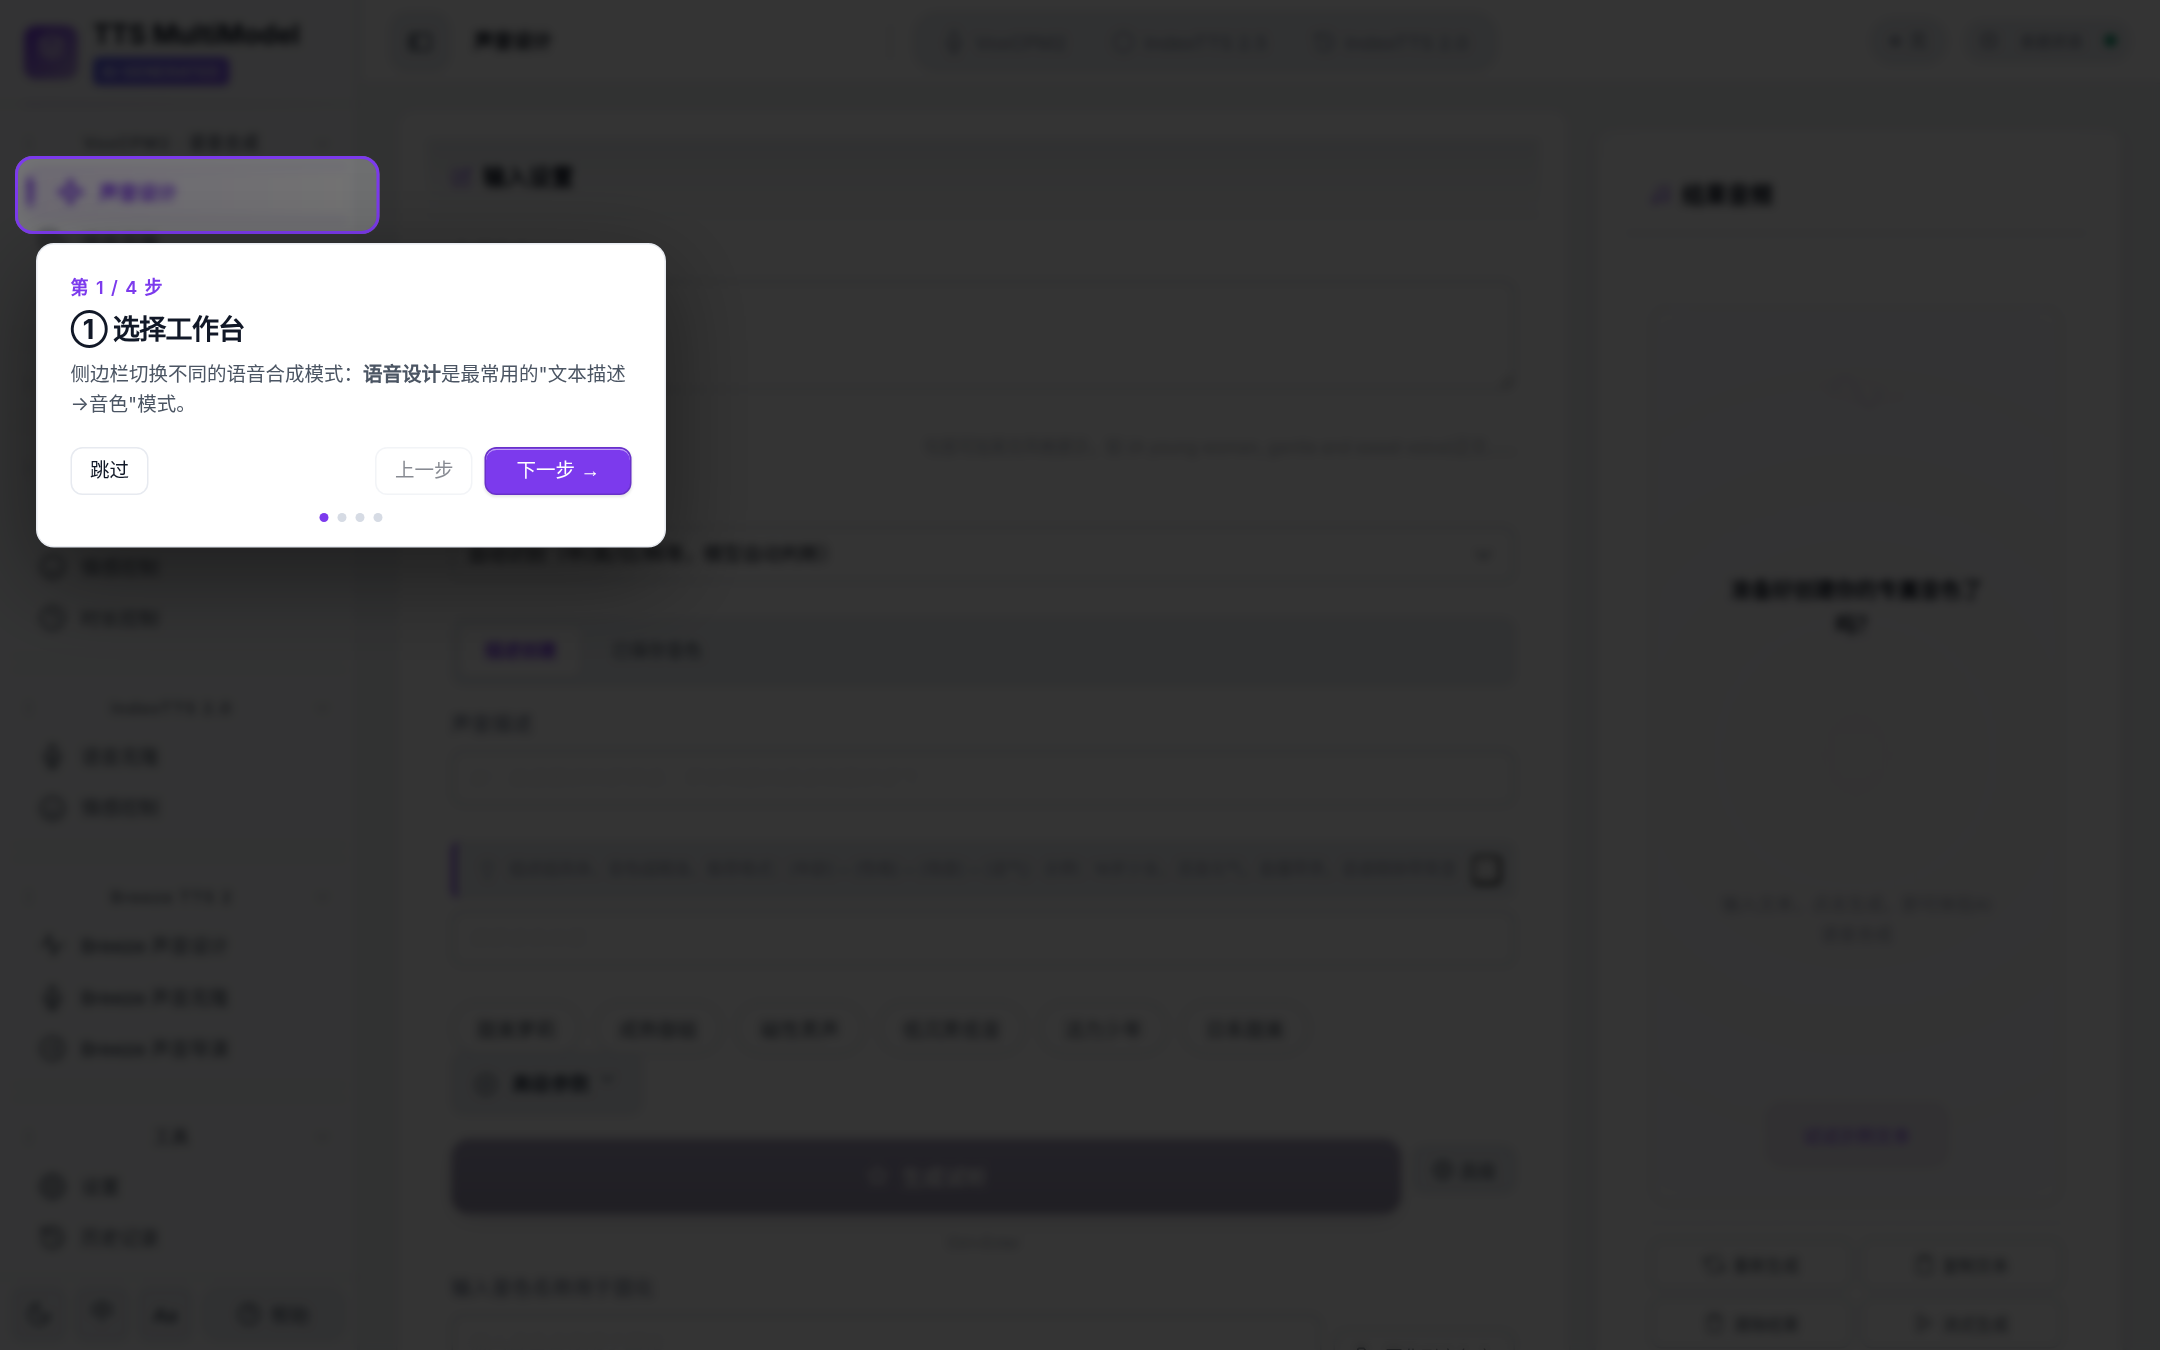
首次打开会出现 4 步新手引导,spotlight 高亮当前操作的菜单项;完成后不再弹出。
主界面(引导完成后)
| 声音设计工作台 | 声音克隆 |
|---|---|
 |
 |
| 文本描述音色,调节语速/音调/情感后生成。 | 上传参考音频克隆音色,支持已保存音色库。 |
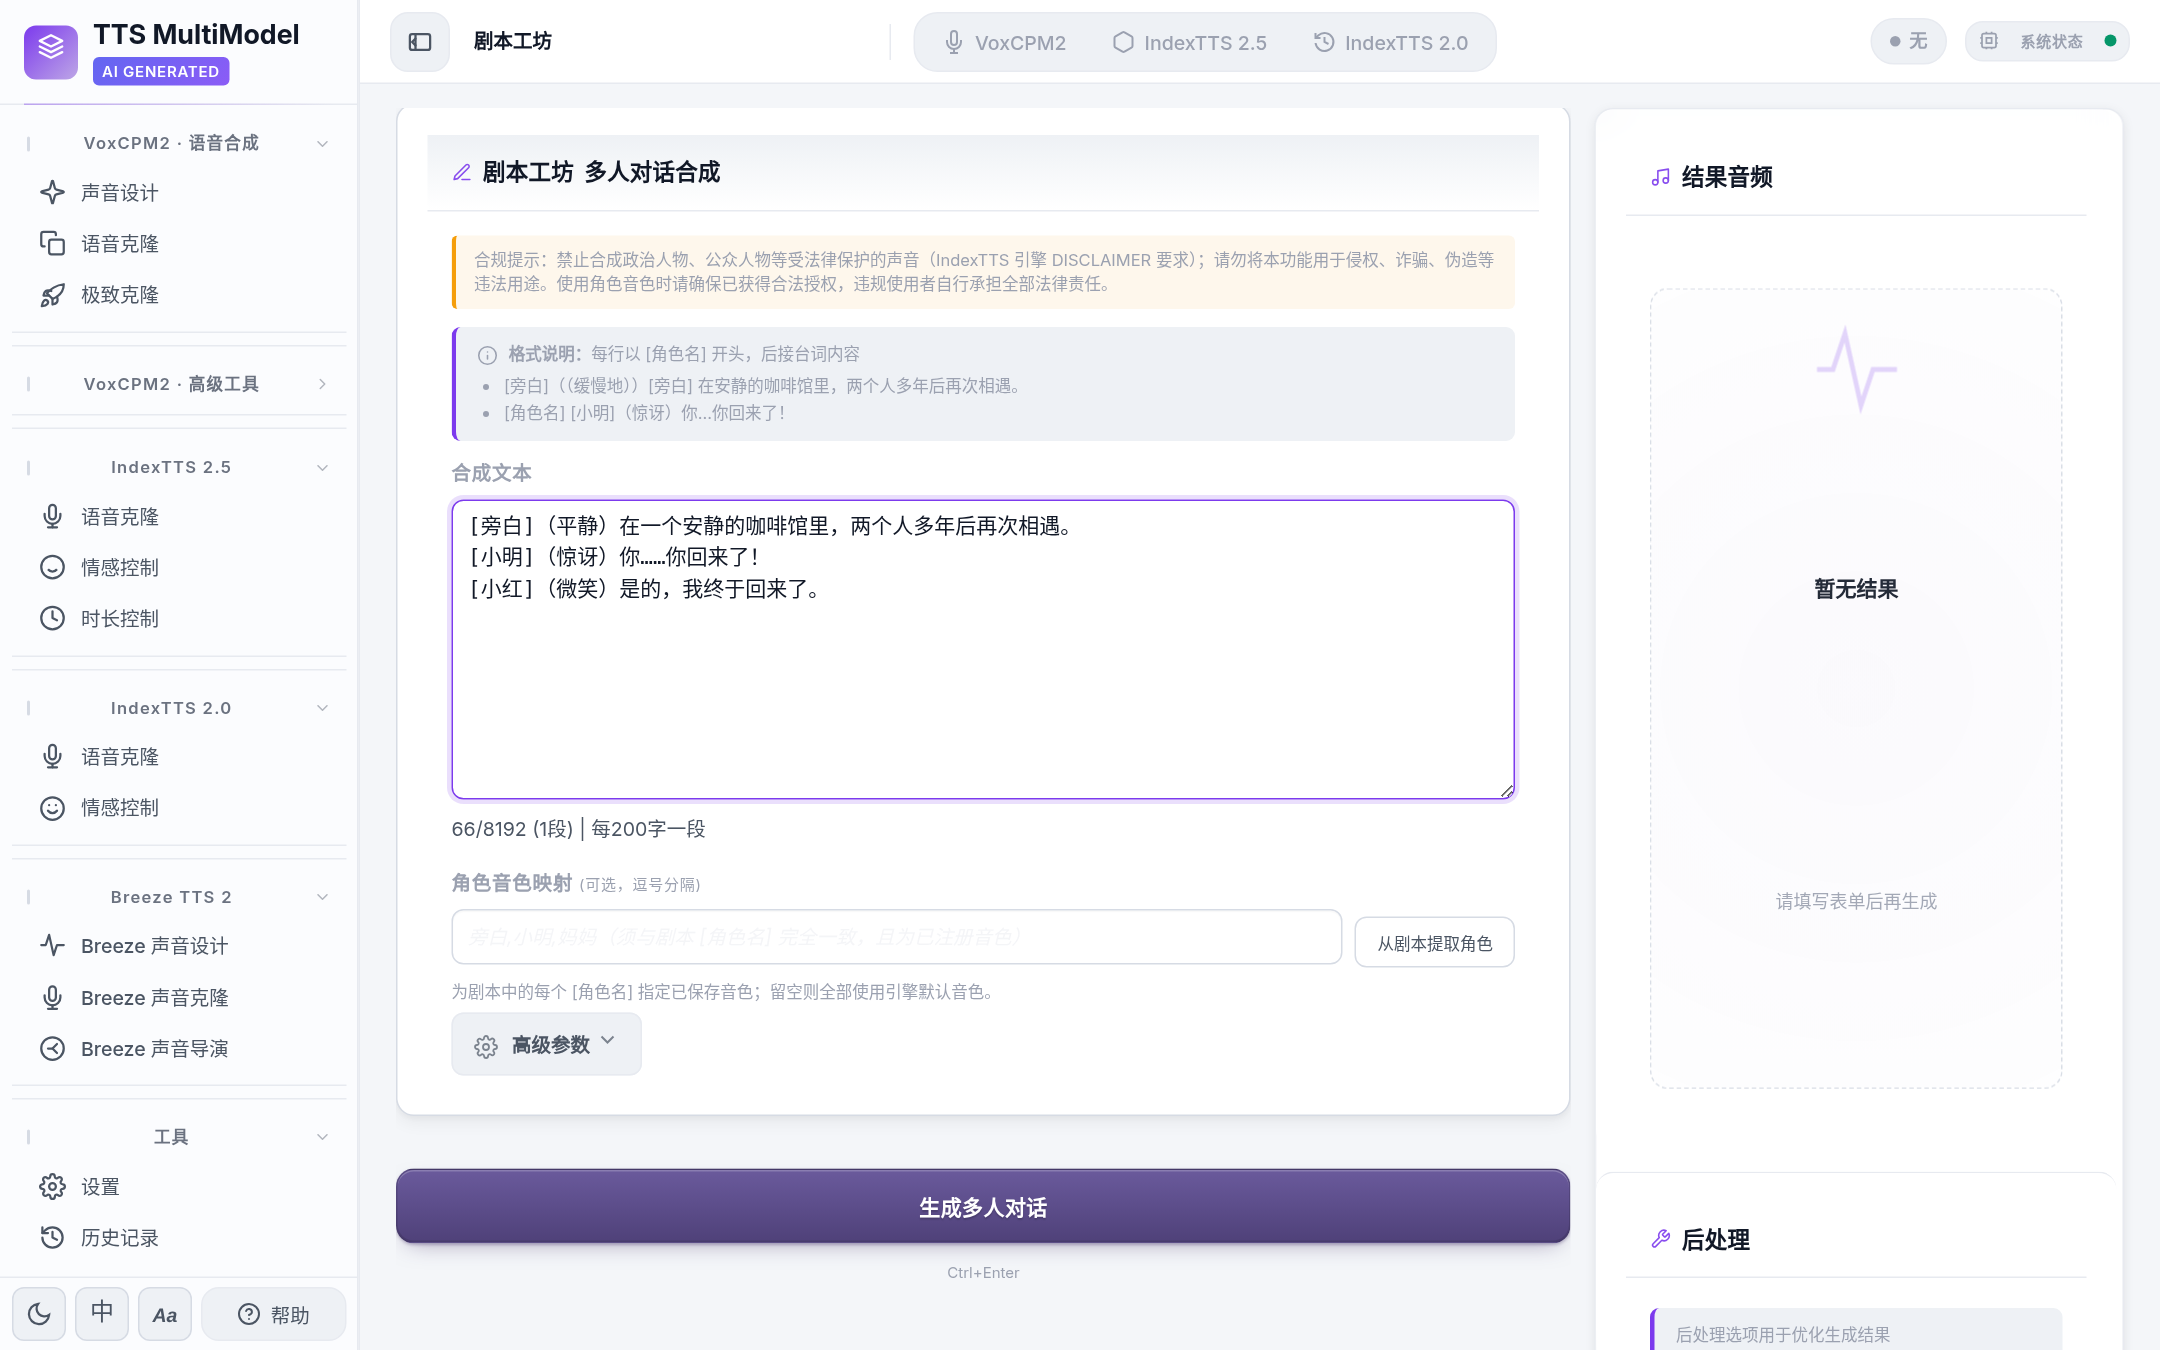
| 剧本工坊(多人对话) | 历史记录 |
|---|---|
 |
 |
按 [角色名] 台词 格式批量配音,可映射角色音色。 |
SQLite 记录生成历史,支持搜索、筛选、分页。 |
环境要求:Windows 10/11 (64-bit) 或 Linux;Python 3.10+(推荐 3.12);本地引擎建议 NVIDIA GPU(6.5 GB+ 显存),无 GPU 时可用 Edge-TTS 在线引擎体验。
git clone https://github.com/ReSerendipity/TTS-MultiModel.git
cd TTS-MultiModelWindows:
install.bat    :: 自动检测系统 Python 或项目内 WinPython,安装依赖并启用 git 钩子
:: 按 scripts/download_models.py 说明下载模型权重后:
start.batLinux:
chmod +x scripts/install.sh && ./scripts/install.sh
./scripts/start.shDocker:
docker compose up -d
# 或拉取随版本发布的 GHCR 镜像(版本号以 config.yaml 为准,当前 v2.7.0)
docker pull ghcr.io/reserendipity/tts-multimodel:2.7.0
启动后访问 http://localhost:7869。最小验证:浏览器打开该地址能看到左侧导航与「声音设计」工作台;或命令行运行 tts-multimodel --help(源码直跑为 python app/integrated_app/cli.py --help)。
模型权重需单独下载:
pip install huggingface_hub modelscope后运行python scripts/download_models.py --all(国内镜像优先,失败回退 ModelScope)。
| 项目 | 说明 |
|---|---|
| 操作系统 | Windows 10/11 (64-bit) 或 Linux(macOS 经 MPS 后端可运行,主要在 Windows 上测试) |
| Python | 3.10+,推荐 3.12;或解压便携 WinPython 到项目根目录完全隔离 |
| GPU | 本地引擎推荐 NVIDIA CUDA(6.5 GB+ 显存);Apple Silicon MPS 亦可;纯 CPU 可用 Edge-TTS 在线引擎 |
| 音频组件 | Windows 需自行安装 Visual C++ Redistributable (x64) 与 SoX;Linux/macOS 用包管理器安装 FFmpeg/SoX |
| 容器 | 提供 Dockerfile 与 docker-compose.yml,GPU 部署需 nvidia-docker runtime |
# 声音设计:文本描述直接生成
tts-multimodel design --text "今天天气不错" --control "warm female voice" -o out.wav

# 零样本声音克隆
tts-multimodel clone --text "你好,很高兴认识你" --reference-audio ref.wav -o clone.wav

# 批量合成(TXT/JSON/CSV,可输出 MP3)
tts-multimodel batch --input texts.txt --output-dir ./outs --reference-audio ref.wav --format mp3
CLI 目前覆盖 VoxCPM2 的 design / clone / batch 三种模式;IndexTTS 合成、极致克隆、剧本工坊、音色库、语音转换与音频编辑、LoRA 训练等请使用 Web UI 或 HTTP API(含 OpenAI 兼容的 POST /v1/audio/speech)。
- 一定要有 GPU 吗? 本地引擎建议 GPU,但项目注册了 Edge-TTS 在线兜底引擎,无 GPU 也能在 CPU 上体验完整界面与在线合成;要跑 VoxCPM2 / IndexTTS 等本地引擎则建议 6.5 GB+ 显存。
- 模型权重从哪里来? 框架本身不含权重。运行
python scripts/download_models.py --all从官方仓库下载到model/对应子目录;也可手动下载。 - LoRA 微调现在能用吗? LoRA 训练链路已随仓库提供(
pip install -e .[training]),但属实验特性、未经真机训练验证,12 GB 显存上训练前需先卸载推理引擎以免 OOM。 - 商用需要注意什么? 项目代码 Apache-2.0 可商用;但各模型权重许可不同——IndexTTS 2.5/2.0 采用 bilibili Model Use License,商用须事先向 bilibili 登记并取得书面授权;Breeze TTS 2 权重与自托管输出仅限研究/非商用,详见
docs/model-cards/。
- 安全策略:docs/SECURITY.md
- 模型卡片与许可:docs/model-cards/
- 运行手册与回滚:docs/SRE_RUNBOOK.md、docs/rollback_sop.md
- 治理规范:ReSerendipity/.github/governance
欢迎报告 Bug(附复现步骤)、提交功能建议或 PR(Fork → 特性分支 → Conventional Commits + DCO Signed-off-by → PR)。安全问题请走 SECURITY.md 披露流程,勿公开开 Issue。使用体验与讨论请到 Discussions。
项目代码基于 Apache License 2.0,Copyright (c) 2026 ReSerendipity。模型权重不随代码分发,各自遵循其官方许可;请勿将本项目用于侵权、伪造或诈骗等违法用途。
TTS MultiModel is a self-hosted, multi-engine Text-to-Speech platform. It unifies six local engines — VoxCPM2, IndexTTS 2.5, IndexTTS 2.0, OpenVoice, Step-Audio-EditX, and Breeze TTS 2 — behind a single FastAPI + HTMX web UI, with an optional Edge-TTS online fallback engine that runs on CPU. One workbench covers voice design, zero-shot / ultimate voice cloning, multi-character script dubbing, voice conversion, and audio editing.
The code is Apache-2.0 and ships with no model weights. You download weights from each model's official repository and comply with that model's own license before use (see "Model licenses" below).
- Six engines, one registry: VoxCPM2 / IndexTTS 2.5 / IndexTTS 2.0 / OpenVoice / Step-Audio-EditX / Breeze TTS 2, switched from a declarative registry; Edge-TTS acts as a CPU-friendly online fallback.
- Voice cloning: zero-shot cloning from a short reference clip; "ultimate clone" pairs reference audio with its transcript for finer timbre fidelity.
- Voice design: describe the target timbre in plain language (e.g. "warm, clear female voice") and synthesize without any reference audio.
- Script dubbing: assign speakers line by line in a multi-character script and batch-render all lines.
- Streaming & batching: SSE streaming for long text; batch jobs resume from checkpoints, with all history kept in SQLite.
- Multi-backend, multi-language UI: NVIDIA CUDA / Apple MPS / CPU auto-detected; UI ships in Simplified/Traditional Chinese, English, Japanese, and Korean.
Clients (web UI / CLI / OpenAI-compatible API) → FastAPI engine registry → six local engines + Edge-TTS online fallback → SQLite history / outputs / personas.
Captured live from source: python app/clean_launch.py on http://127.0.0.1:7869. No model weights downloaded, no synthesis triggered; empty states are shown as-is with engines unloaded.
First-run onboarding
A 4-step walkthrough appears on first launch, spotlighting the current menu item; it does not reappear after completion.
Main UI (after onboarding)
| Voice design workbench | Voice cloning |
|---|---|
|
|
| Describe the timbre, tune speed/pitch/emotion, then generate. | Upload a reference clip to clone a voice; saved personas library included. |
| Script workshop (multi-character) | Generation history |
|---|---|
|
|
Batch dub lines as [character] dialogue, map character voices. |
SQLite generation history with search, filter, and pagination. |
Requirements: Windows 10/11 (64-bit) or Linux; Python 3.10+ (3.12 recommended); a NVIDIA GPU with 6.5 GB+ VRAM for local engines, or Edge-TTS online fallback on CPU.
git clone https://github.com/ReSerendipity/TTS-MultiModel.git
cd TTS-MultiModelWindows:
install.bat    :: auto-detects system Python or bundled WinPython, installs deps, enables git hooks
:: download model weights per scripts/download_models.py, then:
start.batLinux:
chmod +x scripts/install.sh && ./scripts/install.sh
./scripts/start.shDocker:
docker compose up -d
# or pull the versioned GHCR image (tag follows config.yaml, currently v2.7.0)
docker pull ghcr.io/reserendipity/tts-multimodel:2.7.0
Then open http://localhost:7869. Sanity check: the left sidebar and the "Voice design" workbench render in the browser, or run tts-multimodel --help (from source: python app/integrated_app/cli.py --help).
Weights are downloaded separately:
pip install huggingface_hub modelscope, thenpython scripts/download_models.py --all(mirror-first, falling back to ModelScope).
| Item | Details |
|---|---|
| OS | Windows 10/11 (64-bit) or Linux (macOS runs via the MPS backend; primary testing is on Windows) |
| Python | 3.10+, 3.12 recommended; or extract portable WinPython into the repo root for full isolation |
| GPU | Local engines prefer NVIDIA CUDA (6.5 GB+ VRAM); Apple MPS works; Edge-TTS online engine runs on CPU |
| Audio | Windows needs the VC++ Redistributable (x64) and SoX; Linux/macOS use package-manager FFmpeg/SoX |
| Containers | Dockerfile + docker-compose.yml provided; GPU deployment needs the nvidia-docker runtime |
# Voice design: synthesize from a text description
tts-multimodel design --text "Good weather today." --control "warm female voice" -o out.wav

# Zero-shot voice clone
tts-multimodel clone --text "Nice to meet you." --reference-audio ref.wav -o clone.wav

# Batch synthesis (TXT/JSON/CSV, MP3 output)
tts-multimodel batch --input texts.txt --output-dir ./outs --reference-audio ref.wav --format mp3
The CLI currently covers VoxCPM2 design / clone / batch. IndexTTS synthesis, ultimate clone, script workshop, personas, voice conversion/audio editing, and LoRA training are available via the web UI or the HTTP API (including the OpenAI-compatible POST /v1/audio/speech).
- Do I need a GPU? Local engines prefer one, but the registered Edge-TTS fallback lets you explore the full UI on CPU; run VoxCPM2 / IndexTTS etc. with 6.5 GB+ VRAM.
- Where do model weights come from? The framework bundles none. Run
python scripts/download_models.py --allto fetch them into the matchingmodel/subdirectories, or download manually. - Is LoRA training ready? The training path ships in-repo (
pip install -e .[training]) but is experimental and not yet validated on real hardware; unload inference engines first on a 12 GB card to avoid OOM. - Can I use this commercially? The code is Apache-2.0, but weight licenses differ — IndexTTS 2.5/2.0 use the bilibili Model Use License and require prior written registration for commercial use; Breeze TTS 2 weights and self-hosted outputs are research/non-commercial only. See
docs/model-cards/.
- Security policy: docs/SECURITY.md
- Model cards & licenses: docs/model-cards/
- Runbook & rollback: docs/SRE_RUNBOOK.md, docs/rollback_sop.md
- Governance: ReSerendipity/.github/governance
Bug reports (with repro steps), feature requests, and PRs are welcome (Fork → feature branch → Conventional Commits with DCO Signed-off-by → PR). For security issues, follow the disclosure process in SECURITY.md rather than opening a public issue. Questions and show-and-tell belong in Discussions.
Project code is licensed under Apache License 2.0, Copyright (c) 2026 ReSerendipity. Model weights are not bundled and follow their own licenses; please do not use this project for infringement, forgery, fraud, or any unlawful purpose.
如果这个项目对你有帮助 / If this project is useful, please star it. ⭐