Skip to content
View kunkunblueberry's full-sized avatar
  • Beijing
  • 13:31 (UTC -12:00)

Highlights

  • Pro

Block or report kunkunblueberry

Block user

Prevent this user from interacting with your repositories and sending you notifications. Learn more about blocking users.

You must be logged in to block users.

Content in all repositories owned by your account will be closed.
Maximum 250 characters. Please don’t include any personal information such as legal names or email addresses. Markdown is supported. This note will only be visible to you.
Report abuse

Contact GitHub support about this user’s behavior. Learn more about reporting abuse.

Report abuse
kunkunblueberry/README.md

KUNKUN

AI Systems / LLM Inference · vLLM / vLLM-Omni · C++ / CUDA / Python
From CUDA kernels and a hand-built runtime up to vLLM upstream — source first, minimal scope, verified changes.

a small line-art dog

Selected Work

  • LLM Inference Systems — built and optimized inference runtimes across scheduling, KV cache, memory management, and model execution · C++ / CUDA / Python
  • Prefix Cache & Cross-Stage Inference — designed cache lifecycle and state-management abstractions for cross-stage intermediate-state reuse in multimodal inference · vLLM / vLLM-Omni
  • Multimodal Serving & Scheduling — worked on cross-stage execution, request batching, and scheduling for autoregressive and diffusion pipelines · Distributed Inference / PyTorch

Open Source

  • vllm-project/vllm-omni — cross-stage inference, prefix caching, batching, and image-generation infrastructure · #7902 #7920 #8134 #8174
  • ThinkFlowLab/vllm-rlt — integrated Nanbeige4.2 with PD serving and identified model/serving integration issues · #77
Contribution Graph

a snake eating my contribution graph

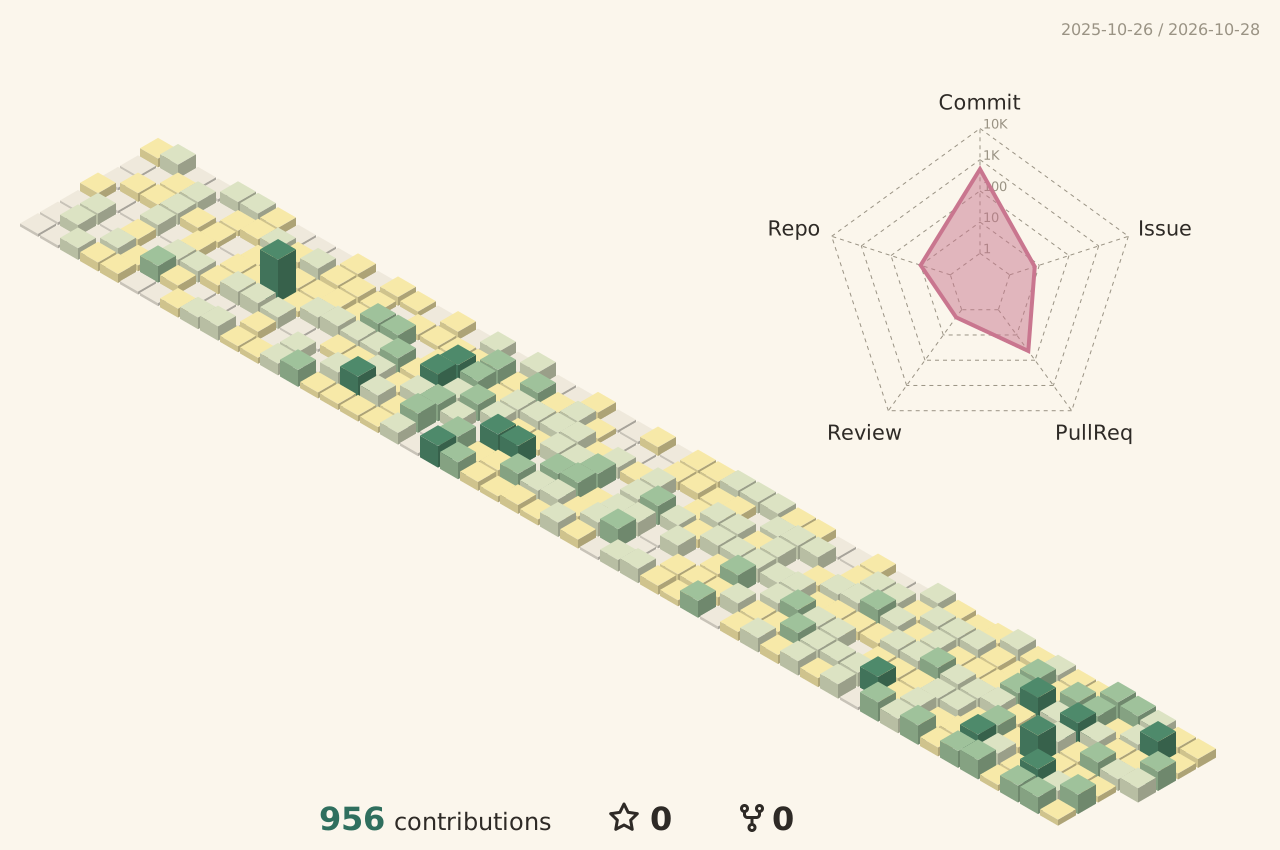
3D isometric contribution graph

Language mix: Python 30%, C++ 53%, CUDA 12%, Shell 2%, C 1.5%, HTML 1%, other 0.5%

Elsewhere

GitHub @kunkunblueberry
Email 1833921874@qq.com

Pinned Loading

  1. vllm vllm Public

    Forked from vllm-project/vllm

    A high-throughput and memory-efficient inference and serving engine for LLMs

    Python

  2. vllm-project/vllm-omni vllm-project/vllm-omni Public

    A framework for efficient model inference with omni-modality models

    Python 7.4k 2k